
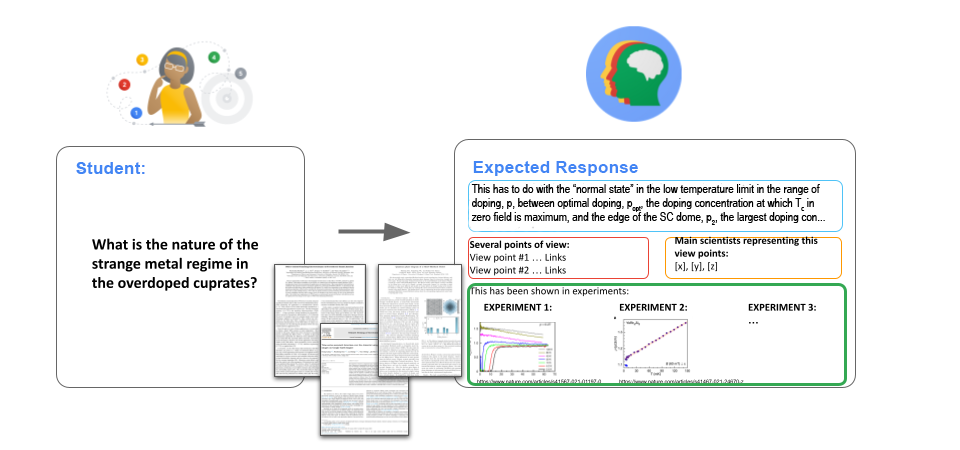
Google Research Evaluates Large Language Models on Complex Superconductivity Research Questions
Google Research has published an exploration into the capabilities of Large Language Models (LLMs) within the specialized field of superconductivity. The study focuses on testing how these advanced AI systems handle highly technical research questions, marking a significant intersection between artificial intelligence and material science. By evaluating LLMs on their ability to process and respond to complex scientific inquiries, the research highlights the potential for AI to assist in high-level academic and industrial research. This initiative falls under the broader umbrella of education innovation, seeking to understand how automated systems can support the next generation of scientific discovery and technical learning in physics and engineering.
Key Takeaways
- Google Research is actively testing the proficiency of Large Language Models (LLMs) in the domain of superconductivity.
- The initiative aims to evaluate how AI handles complex, technical research questions in specialized scientific fields.
- This research represents a significant step in education innovation and scientific tool development.
In-Depth Analysis
LLMs in Specialized Scientific Domains
Google Research is investigating the performance of Large Language Models when applied to the intricate field of superconductivity. Unlike general-purpose queries, superconductivity research requires a deep understanding of condensed matter physics and material science. By subjecting LLMs to these specific research questions, Google aims to identify the current strengths and limitations of AI in interpreting high-level scientific data and theoretical frameworks. This testing is crucial for determining if AI can move beyond simple information retrieval to become a viable partner in complex scientific reasoning.
Advancing Education Innovation
The project is categorized as an effort in education innovation. By refining how LLMs interact with specialized research topics, there is a clear path toward creating more sophisticated educational tools for students and researchers. These tools could potentially provide nuanced explanations of difficult concepts or assist in the synthesis of existing literature within the superconductivity space. The focus remains on how these models can be tuned to maintain accuracy and utility in a field where precision is paramount.
Industry Impact
The testing of LLMs on superconductivity questions has broad implications for the AI industry and the scientific community. If LLMs can demonstrate reliability in such a specialized niche, it paves the way for AI-driven discovery in other areas of physics and chemistry. For the AI industry, this signifies a shift toward domain-specific expertise, moving away from generalist models toward systems that can provide value in high-stakes research environments. Furthermore, it highlights the growing role of AI as a foundational tool in accelerating the pace of material science innovation.
Frequently Asked Questions
Question: What is the primary focus of this Google Research study?
The study focuses on testing the ability of Large Language Models (LLMs) to answer and process complex research questions specifically related to the field of superconductivity.
Question: How does this research contribute to education innovation?
It explores how advanced AI can be utilized to handle specialized scientific knowledge, which can lead to the development of better educational resources and research aids for complex technical subjects.

